
I am currently a PhD student in the Department of Data Science and AI at Monash University, luckily advised by Prof. Tien-Tsin Wong and Prof. Jianfei Cai. I received B.S. and M.Phil. in Computer Science from Beijing Jiaotong University.
I am interested in Image/Video Generation and World Models.
📖 Education
- 2024.11 - now, Doctor of Philosophy, Department of Data Science and AI, Monash University, Melbourne.
- 2020.06 - 2024.06, Master of Computer Science, School of Computer and Information Technology, Beijing Jiaotong University, Beijing.
- 2016.09 - 2020.06, Bachelor of Computer Science, School of Computer and Information Technology, Beijing Jiaotong University, Beijing.
🔥 News
- 2026.10: 🔥 We release Oneira, an open-world interaction video world model.
- 2026.06: 🎉 One paper ATA is accepted by ECCV 2026.
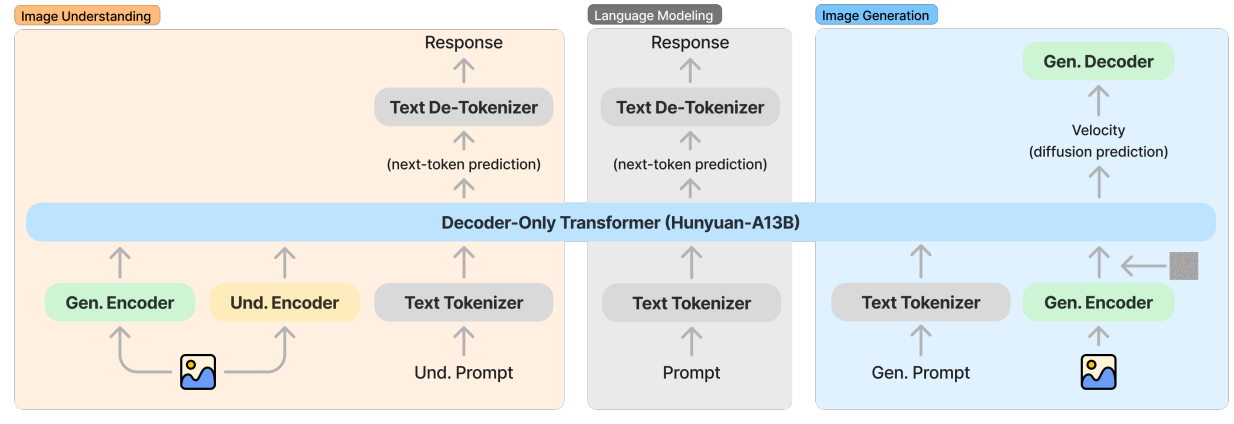
- 2025.09: 🔥 We release the HunyuanImage 3.0 Technical Report.
- 2025.06: 🎉 One paper VLIPP is accepted by ICCV 2025.
- 2024.01: 🎉 One paper Neural Field Classifier is accepted by ICLR 2024.
- 2023.08: 🎉 SDFStudio has supported S3IM.
- 2023.08: 🔥 We release S3IM(⭐️200+).
- 2023.07: 🎉 One paper S3IM is accepted by ICCV 2023.
📝 Publications and Manuscripts
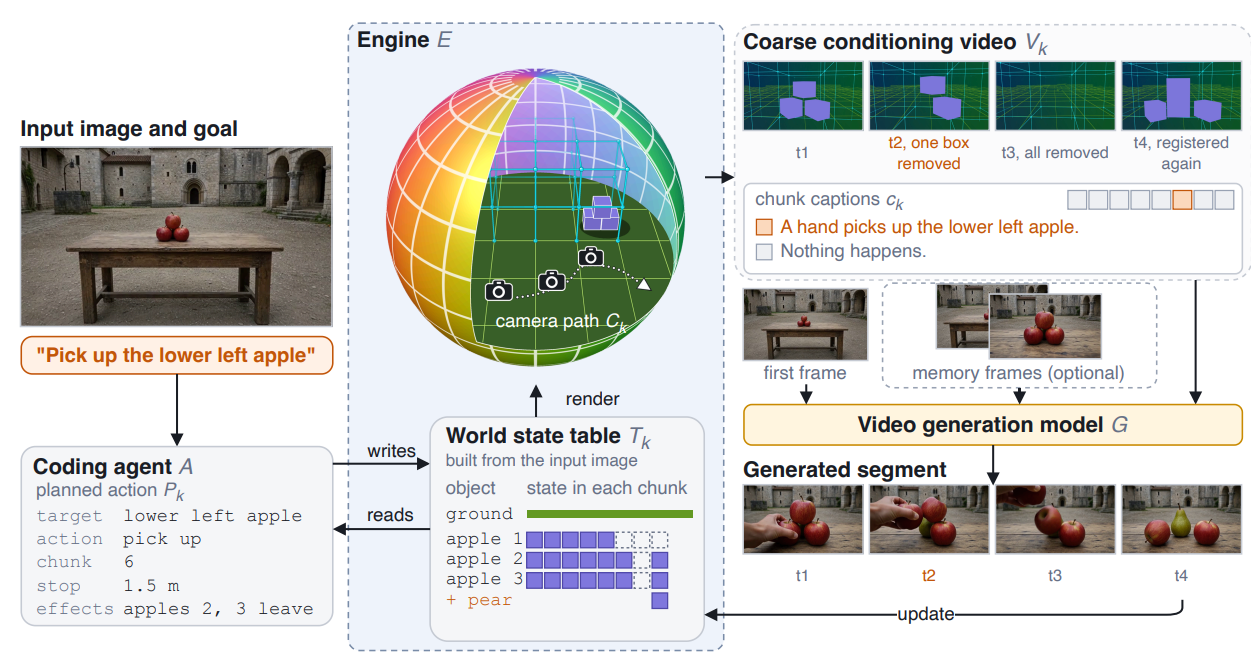
Oneira: From Open-Ended Generation to Open-World Interaction in Video World Models.
Xindi Yang, Baolu Li, Liam Lee, Zhenfei Yin, Songxin Zhang, Zhuoyang Song, Xu Jia, Jianfei Cai, Tien-Tsin Wong, Bingyi Jing, Mengyue Yang.
- Oneira is an interactive video world model built around an explicit world state managed by a coding agent. It enables instance-level interaction with objects that emerge during open-world exploration, and the consequences of each interaction persist across long horizons.
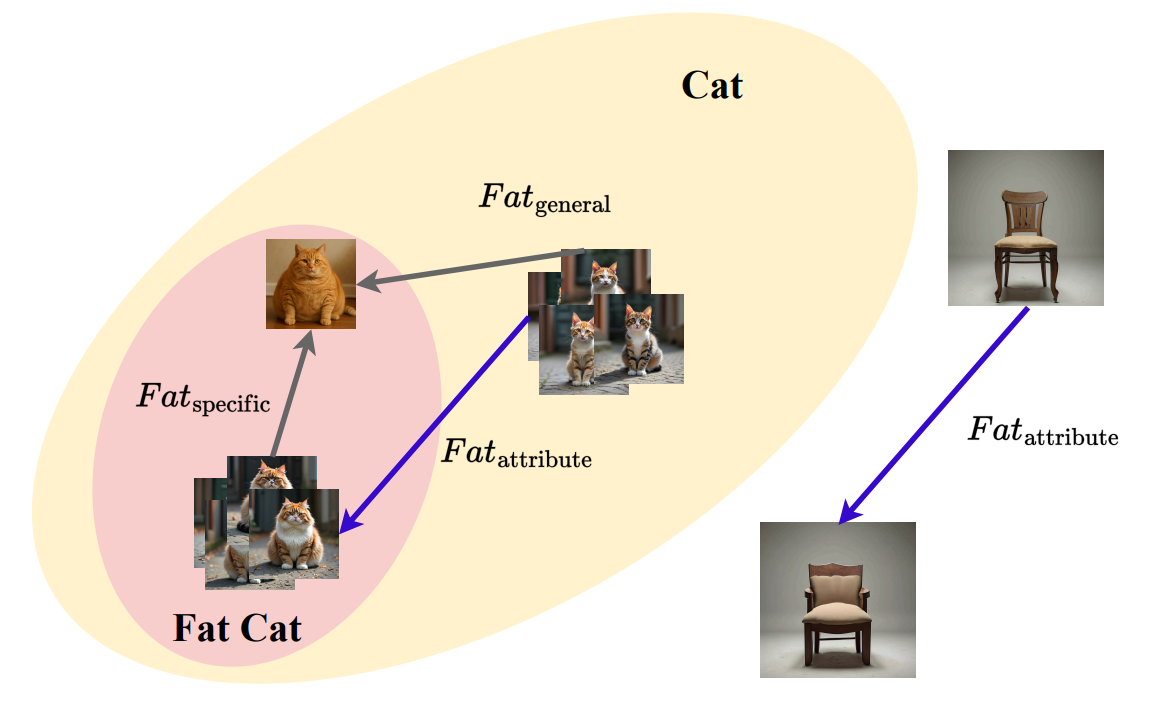
Xindi Yang, Yicheng Wu, Cheng Zhang, Jianfei Cai, Tien-Tsin Wong.
- ATA finds attribute directions (e.g., aging, fatness, emotion) in the latent space of a pretrained visual autoregressive model from a single reference image, enabling disentangled, continuous and composable attribute control without retraining.
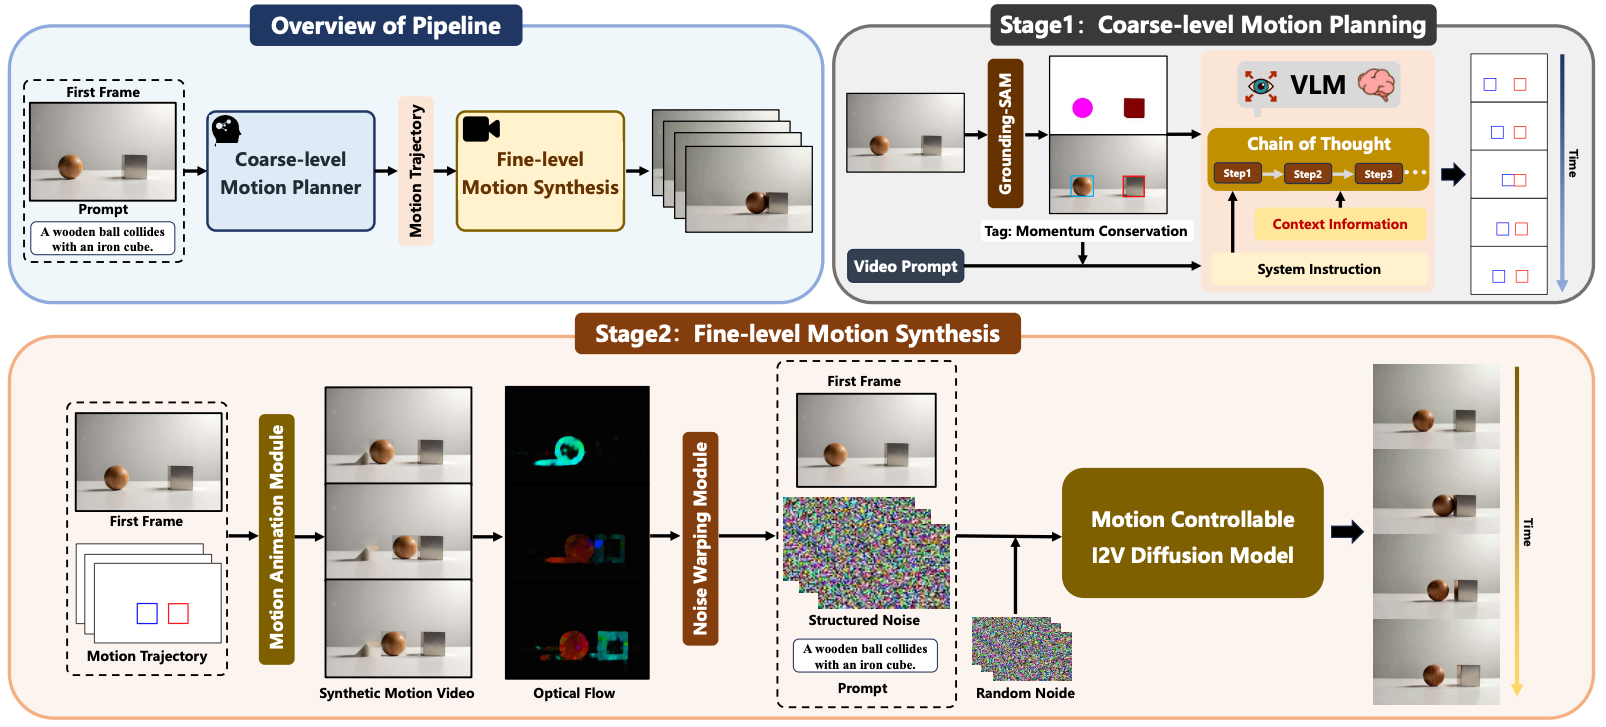
Xindi Yang*, Baolu Li*, Yiming Zhang, Zhenfei Yin, Lei Bai, Liqian Ma, Zhiyong Wang, Jianfei Cai, Tien-Tsin Wong, Huchuan Lu, Xu Jia (*equal contribution).
- VLIPP is a two-stage image-to-video generation framework that explicitly incorporates physics with vision and language informed physical prior.

Neural Field Classifiers via Target Encoding and Classification Loss.
Xindi Yang, Zeke Xie, Xiong Zhou, Boyu Liu, Buhua Liu, Yi Liu, Haoran Wang, Yunfeng Cai, Mingming Sun.
- Neural Field Classifiers via Target Encoding and Classification Loss can significantly outperform the standard regression-based neural field counterparts.

S3IM: Stochastic Structural SIMilarity and Its Unreasonable Effectiveness for Neural Fields.
Zeke Xie*, Xindi Yang*, Yujie Yang, Qi Sun, Yixiang Jiang, Haoran Wang, Yunfeng Cai, Mingming Sun (*equal contribution).
🎖 Honors and Awards
- 2023, Outstanding Intern of the Year, Baidu Research
- 2016-2022, Model Student of Academic Records of Beijing Jiaotong University
- 2018, National Contemporary Undergraduate Mathematical Contest IN Modeling in China, First Prize in Beijing region
📝 Academic Service
- Journal Review: IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), IEEE Transactions on Visualization and Computer Graphics (TVCG), Computer Graphics Forum (CGF)
- Conference Review: ICLR, NeurIPS, ICCV, ECCV, CVPR